
🤔 What is it?
The k-NN algorithm is a widely-used supervised learning technique that can handle classification and regression tasks. It is an instance-based learning method, which means that it stores the training instances and uses them at prediction time to make decisions. The algorithm uses proximity to determine the grouping of a new data point, based on the assumption that similar data points tend to cluster together. What makes it unique is its non-parametric nature, which means that it doesn’t make any assumptions about the underlying distribution of the data. As a result, it can be used to address non-linear separable data in classification tasks and non-linear regression problems. This property of k-NN makes it a valuable tool for various applications in machine learning.
🕵️♂️ How does it work?
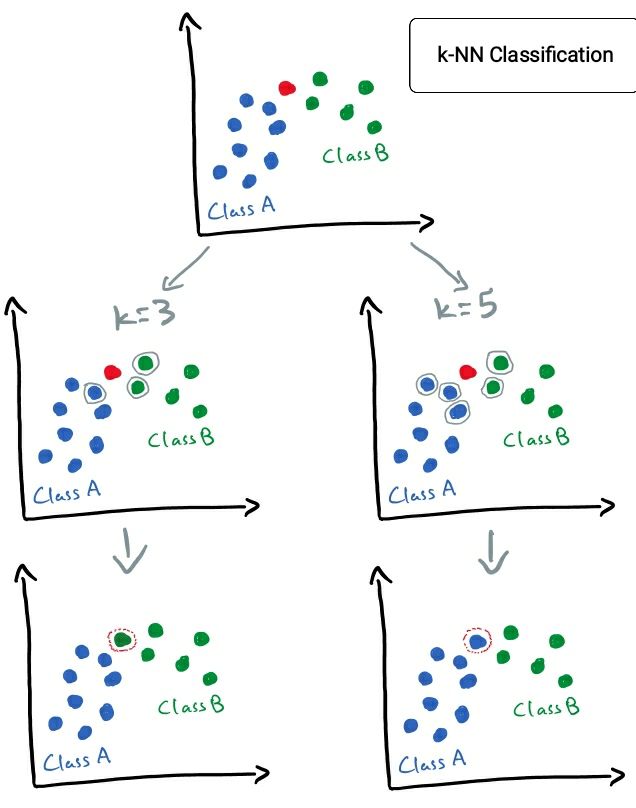
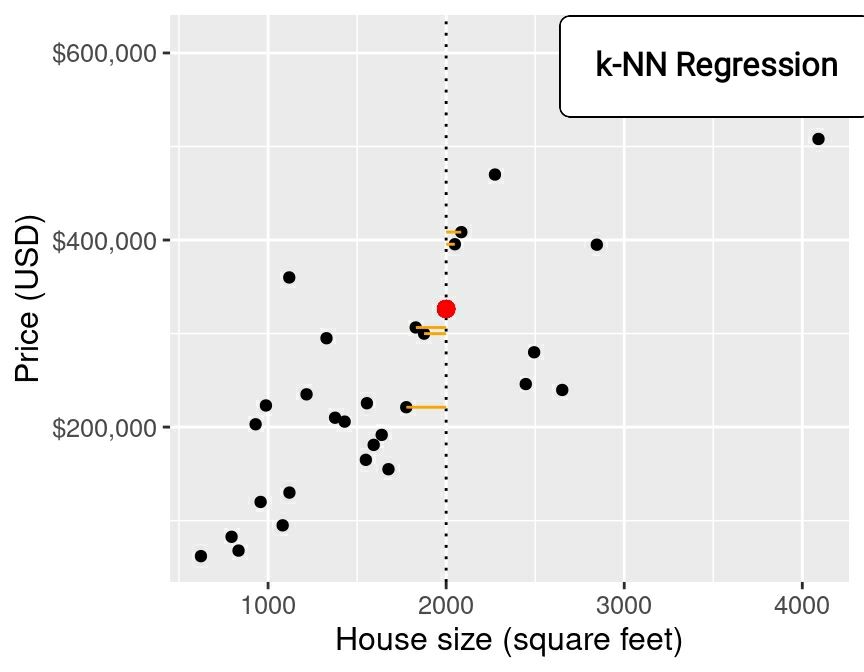
The k-NN algorithm works by finding the k data points in the training set that are closest in distance (e.g. Euclidean, Manhattan, Cosine) to the new data point, and then assigning the new data point to the class that is most common among its k nearest neighbors in classification tasks or predicting the target value of the new data point based on the average of the target values of its k nearest neighbors in regression tasks. The value of k is a user-defined parameter that controls the number of neighbors considered for classification or regression.
💡 Why is it useful?
The k-NN algorithm is easy to understand and implement, making it a popular choice for beginners in machine learning. Since the k-NN algorithm has no assumptions about the underlying distribution of the data, it can be used for a wide range of data types and structures.
👨💻 My personal story
When I first started learning machine learning, the k-NN algorithm was one of the first algorithms I encountered. I remember feeling intimidated by some of the more complex algorithms, but k-NN seemed simple and intuitive. I used it to classify handwritten digits in the MNIST dataset and was impressed by its accuracy and speed. As I continued to study machine learning, I’ve moved on to more advanced techniques (e.g. Neural Networks). However, I still appreciate the simplicity and versatility of k-NN.
📚 Who should learn it?
The k-NN algorithm is a useful tool to have for anyone learning AI. It can help you -as it helped me personally- to understand later on even more complex and powerful AI algorithms and be a better machine learning engineer.
🗣️ Let’s talk!
Do you have any experience using the k-NN algorithm? What applications have you used it for? If anyone would like to know more or has questions, feel free to ask in the comments below.



 Efstathios Chatzikyriakidis
